
How to Evaluate AI for Insurance Claims Review
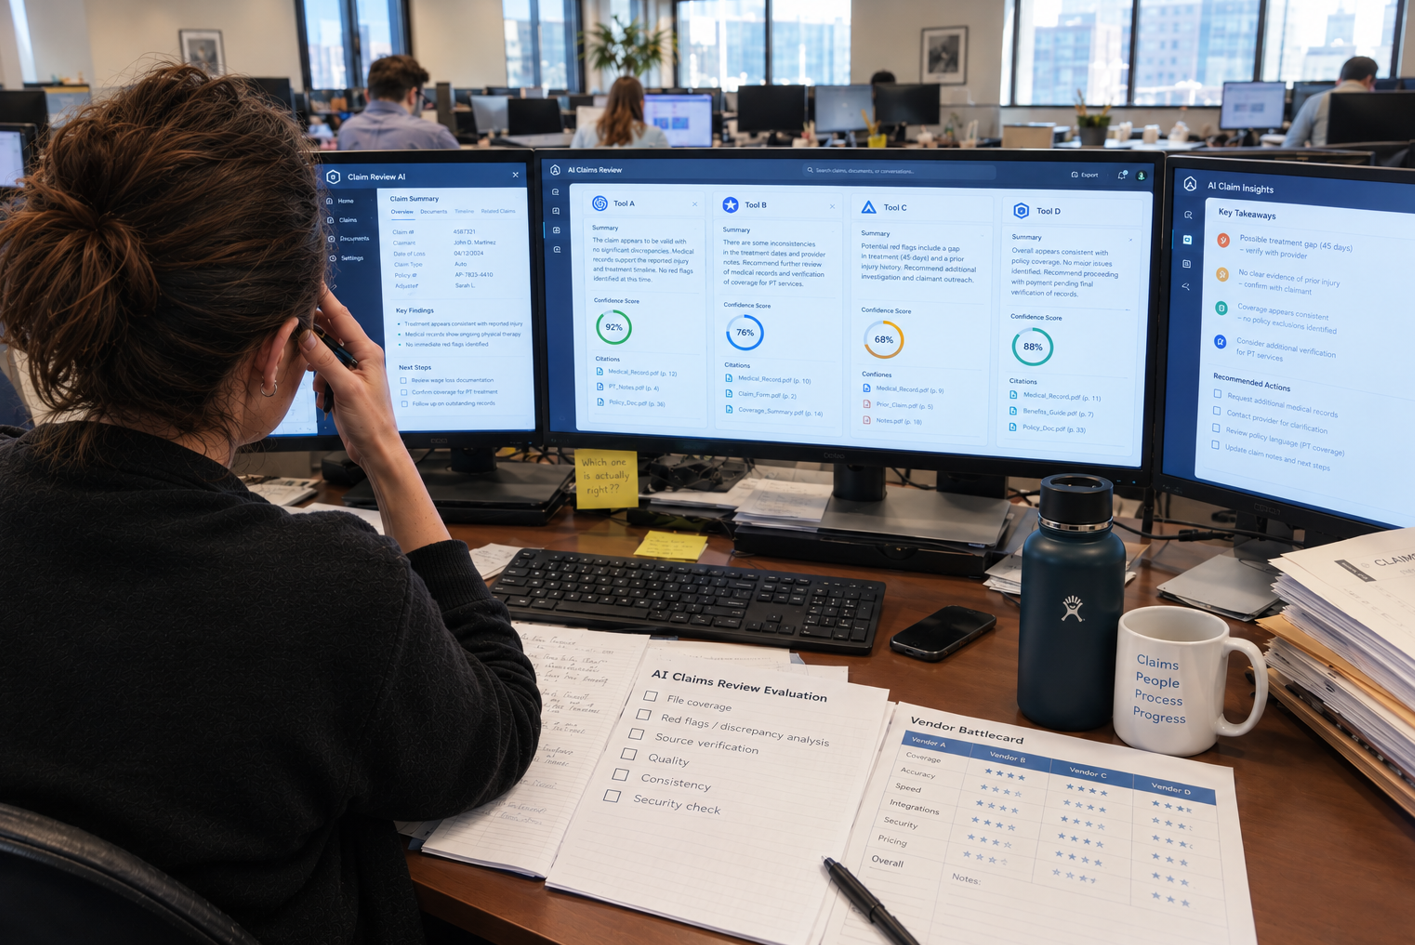
Evaluating claims AI based on a polished demo or an impressive summary is not enough. Insurers should test it against the same incomplete, inconsistent, document-heavy files their teams handle every day.
The real test is whether the tool can analyze the relevant evidence across a long file, answer specific claims questions accurately, show where its findings came from, and produce outputs the team can use.
For claims leaders, operations teams, and insurance innovation leaders, this requires a different approach to evaluation. The objective is to establish whether AI helps an experienced reviewer reach a defensible conclusion faster, with less manual searching and no loss of important context.
A comprehensive answer does not prove a comprehensive review
A fluent answer can create a misleading impression of completeness. It may describe a claimant's history in confident language, organize the response into clear sections, and appear to account for the entire file.
That appearance does not establish how much evidence the system considered.
Brad Schneider, CEO of Nomad Data, describes a recurring problem in evaluations of consumer-grade tools:
"They produce very eloquent and what look like very comprehensive answers."
Yet, he explains, the system may have retrieved only a few snippets and filled gaps with unsupported assumptions.
An adjuster or underwriter can therefore believe they are seeing all the facts while receiving only a subset. A missing work-status note, conflicting account, or later medical assessment may change the interpretation of everything else.
This risk should be tested directly. Tools differ in their processing and retrieval methods, and a familiar chat interface reveals little about those differences. Insurers should ask what was processed, what limits apply, and how the vendor demonstrates completeness.
The evaluation must look beyond the quality of the prose to the quality and coverage of the evidence.
Start with representative files and a reliable benchmark
The insurer should select the evaluation files. Vendor-provided examples can explain a product, but the pilot should reflect the insurer's own workload.
A useful set includes typical claims alongside difficult cases: long medical histories, poor scans, duplicate records, conflicting statements, varied document types, and files that grew through multiple review cycles.
The first benchmark files should also be exceptionally well understood. Schneider recommends files that are already thoroughly documented and summarized, with important dates and timelines established.
This creates something concrete to test against. Reviewers can compare the AI's account with known events, material evidence, unresolved questions, and the reasoning behind previous conclusions.
Continental General's published experience illustrates this approach. Its team used historical claims with known outcomes, compared responses with its prior work, and refined prompts and outputs through frontline feedback.
A benchmark still requires judgment. The existing summary may contain an omission. When AI finds something additional, reviewers should inspect the source before classifying it as an error or a useful discovery.
Once the tool performs well on familiar files, the pilot should expand to additional cases that were not used for configuration. That helps establish whether the improvement carries beyond the initial examples.
Test the complete document set
Complex claims review depends on connecting information across documents.
Medical records may describe treatment and functional limitations. Correspondence may explain a missing record or a disputed date. Reports, forms, bills, policy documents, and supporting materials may supply evidence that changes how a medical history should be interpreted.
A tool should therefore be evaluated on the complete document set relevant to the task. Separate summaries of individual documents do not, by themselves, demonstrate that the system can reconcile evidence across the claim.
Before testing answers, the team should confirm what the system successfully ingested and what remains unavailable or unreadable. An upload confirmation alone does not prove successful analysis.
The pilot should include checks for difficult tables, scanned forms, checkboxes, handwritten entries, and inconsistent layouts. A misread date or a value assigned to the wrong table row can undermine the final answer before reasoning begins.
The insurer should also test how the system handles duplicate documents and new records. Repetition should not become apparent corroboration, and later evidence should not disappear beneath older material.
Test specific retrieval and broad synthesis separately
A tool can excel at finding an isolated fact while struggling to assemble a complete account.
Consider a narrow question like "What did the patient report happening with their left knee?"
If only a few paragraphs address the subject, a retrieval-based tool may locate those passages and answer accurately.
That success does not establish that it can summarize every relevant event across thousands of pages.
There are broader questions that serve as a useful stress test: summaries of particular dates, event types, or subjects mentioned throughout the file. These require the system to connect many pieces of evidence rather than retrieve a small number of passages.
A balanced question set should include:
- Specific facts: What did the claimant report about the left knee, and where is it documented?
- Complete timelines: List the documented work restrictions, their effective dates, and the providers who issued them.
- Changes: How did the claimant's reported functional limitations change over time?
- Conflicts: Which records disagree about the injury, treatment, or ability to work?
- Gaps: What supporting information is absent or insufficient for the review task?
Each question should define the scope and expected output clearly. Where the file does not support an answer, the tool should identify the uncertainty.
Asking the AI whether it read every page may expose a limitation. Schneider notes that some tools acknowledge incomplete review when pressed. However, the system's own assurance is not proof. Completeness should be checked against known evidence and the vendor's explanation of how the task was performed.
Require citations that make verification practical
Every important finding should have a clear path back to its supporting evidence.
A citation should take the reviewer to the relevant document and page or passage. The reviewer should be able to confirm the statement and inspect its surrounding context without conducting another full-file search.
The pilot must test citation quality as well as citation presence. Does the cited passage support the finding? Is the date correct? Does the source describe an observation, a claimant's report, or a provider's assessment? Is contradictory evidence acknowledged?
A statement can have a valid citation and still be incomplete. One note may support a work restriction while another changes it. The reviewer needs both to understand the timeline.
Missing evidence requires care, too. These statements have different meanings:
1. "Not found in the supplied records"
2. "Did not happen"
The output should preserve that distinction.
Nomad Data's medical records summary guide describes source-linked summaries and follow-up Q&A as a way to shorten orientation and verification. In evaluation, the practical measure is how quickly reviewers can inspect the evidence and resolve uncertainty.
Compare quality and total review time
The comparison should measure whether the AI-assisted process produces work at least as good as an experienced reviewer's.
Useful measures include missed material facts, unsupported conclusions, incomplete timelines, incorrect citations, and overlooked conflicts. Findings should also be assessed by consequence: a formatting issue and a missed fact that could change the review deserve different weight.
Consistency matters. Reviewers can ask follow-up questions with slightly different wording and compare the underlying facts. The wording may change, but established dates and documented events should remain stable. Consistency alone does not establish correctness; repeated answers still need source verification.
Time savings should cover the complete task. Include preparing the files, generating outputs, verifying sources, correcting mistakes, asking follow-up questions, and transferring the result into the team's documentation.
A fast answer that requires extensive repair may produce little operational benefit.
RKL's published case study offers a useful example of measuring the workflow rather than generation speed. RKL reported a 70% reduction in Part B claims review time after shifting from manual comparison toward validating AI results and investigating flagged exceptions. That result is specific to RKL's process; each insurer should measure its own outcome.
Evaluate the vendor as a working partner
A pilot should test how the vendor responds when something goes wrong.
Schneider describes two expectations: the partner should explain why the answer is incorrect and be able to customize or adjust the tool to produce the correct result.
The explanation matters. A missed fact might originate in document interpretation, incomplete retrieval, ambiguous instructions, or a mismatch between the workflow and the configured output. Different causes require different corrections.
After a change, the insurer should rerun the original case and additional cases. The aim is to establish that the cause was addressed and that the correction did not create another problem.
This makes evaluation collaborative without making it uncritical. Claims professionals contribute their expertise and review requirements. The vendor demonstrates how the system can apply those requirements reliably.
A vendor that can only improve the appearance of an answer has not demonstrated an improvement in evidence handling.
Confirm security and fit with daily claims work
Accuracy is necessary, but adoption also depends on how easily the tool fits the existing process.
Claims leaders should test the practical steps: obtaining documents, submitting the file, reviewing the output, opening sources, asking follow-ups, and using the result in the claim record or internal review.
Implementation effort should be assessed alongside the capabilities being demonstrated. A team may begin with direct uploads and add integration later. The pilot should distinguish what works immediately from what requires further configuration or technical work.
Security should be evaluated for the actual service and configuration. Relevant questions include access controls, retention and deletion, handling of sensitive information, subprocessors, and whether customer content is used to train shared models. Nomad Data's discussion of AI risks in insurance emphasizes that a product name alone does not establish which protections apply.
Human responsibilities should be explicit. Reviewers need to know which findings require verification, who approves the output, and who owns the final claims decision.
User behavior provides another signal. Schneider says teams are often close to production readiness when reviewers have already made the tool part of their workflow and are enthusiastic about the outputs. That enthusiasm supports the measured quality results; it should not substitute for them.
A practical pilot checklist
Insurers can use the following framework when comparing vendors:
- Representative files: Use insurer-selected claims with realistic volume, quality, and complexity.
- Reliable benchmark: Begin with well-documented files that have established summaries and timelines.
- File coverage: Confirm what was processed and identify unreadable or unsupported material.
- Retrieval and synthesis: Test isolated facts, broad timelines, changes, conflicts, and gaps separately.
- Source verification: Check that material findings link to evidence that supports them in context.
- Quality and consistency: Record omissions, unsupported conclusions, conflicting answers, and their significance.
- Vendor response: Require an explanation of errors, a correction, and testing on additional cases.
- Operational value: Measure total review time and whether outputs fit existing documentation.
- Production readiness: Confirm security, human oversight, acceptable quality, and practical user adoption.
Acceptance criteria should be agreed before the pilot begins. The insurer should define which errors are unacceptable, what improvement would justify adoption, and what remains subject to human review.
Reaching a defensible conclusion faster with Doc Chat
At Nomad Data, we created Doc Chat to handle all parts of a review task: analyzing large, complex document sets, answering specific questions, and producing cited outputs that reflect how a claims team works.
Those outputs can include tailored summaries, timelines, comparisons, and structured findings. Reviewers can investigate further through Q&A and return to the supporting sources. Doc Chat brings these capabilities into a single secure solution designed to support existing insurance workflows. The evaluation should demonstrate that value on the insurer's own files.
The strongest proof is a reviewer who receives usable findings, verifies the evidence, identifies what remains unresolved, and reaches a defensible conclusion with less manual effort. That is the standard claims AI should be expected to meet. For claims teams, that means evaluating more than the first answer: it means testing whether reviewers can follow the evidence, resolve conflicting information, and document their reasoning clearly. A successful pilot should show how Doc Chat supports those steps across representative files, with measurable improvements in review quality and efficiency.
Learn more about how Doc Chat can support the review of complex claims files.
